Actor-Curator: Co-adaptive Curriculum Learning via Policy-Improvement Bandits for RL Post-Training
COLM 2026
Zhengyao Gu*, Jonathan Light*, Raul Astudillo, Ziyu Ye, Langzhou He, Henry Peng Zou, Wei Cheng, Santiago Paternain, Philip S. Yu, Yisong Yue
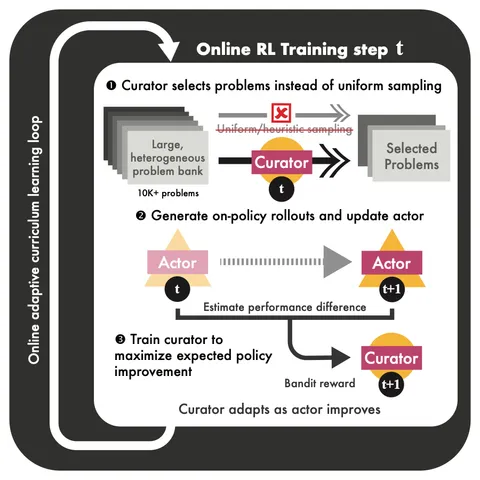
A scalable, fully automated curriculum-learning framework for RL post-training of LLMs. Learns a neural curator that selects training problems to directly maximize expected policy improvement, formulated as a non-stationary bandit with regret guarantees. Delivers +28.6% on AIME2024, +30.5% on ARC-1D, and up to 80% speedup over the strongest baseline. Outstanding Paper Award and Oral (top 3.9% of accepted papers) at the ICLR 2026 Logical Reasoning Workshop.